NewAnthropic
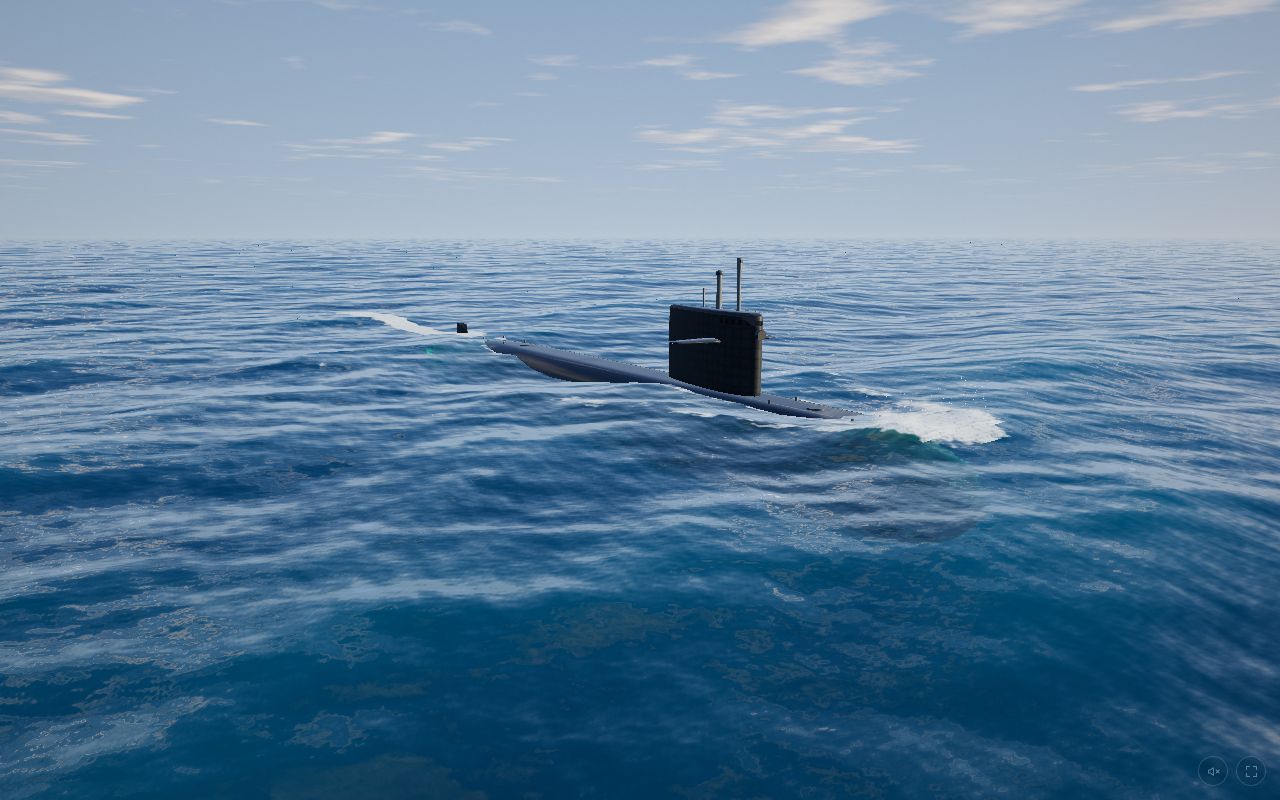
Claude Opus 5.5
Latest build: Diving submarine
- Rating
- New
- Win rate
- None yet
- Cost per build
- Unknown
- Build time
- Unknown
Every model we test, rated by the swarm. Each model has a rating, like a chess rating. A win against a strong model earns more points than a win against a weak one.
| # | Model | Rating | Votes |
|---|---|---|---|
| – | Claude Opus 5.5Anthropic | 0 | |
| – | Claude Fable 5.2Anthropic | 0 | |
| – | Gemini 4 NeonGoogle | 0 | |
| – | Gemini 4 CarbonGoogle | 0 |
A model needs 50 votes before it gets a rank. Grey rows have fewer votes, so their rating can still change a lot. Cost per build is the average API price of one build. Votes for a tie and for “both are bad” count as a draw.